What MTTR measures, and which MTTR people mean
01The short answer#
MTTR is the average time an incident lasts, but the R hides four different things. Two teams comparing their MTTR are usually comparing two different measurements.
- Respond
- From the alert to someone starting work.
- Repair
- From starting work to the fix being in.
- Recover
- From failure to customers being fine again.
- Resolve
- Until the follow-up that stops it happening again is done.
02What to actually track#
Track two numbers you can act on: how long until someone knew, and how long until customers were fine again. The first measures your alerting, the second your fix, and neither rewards closing a ticket early.
Most of the time between those two is spent finding out what changed. That's the part worth attacking, because it's the same detective work on every incident.
03How UpControl shortens it#
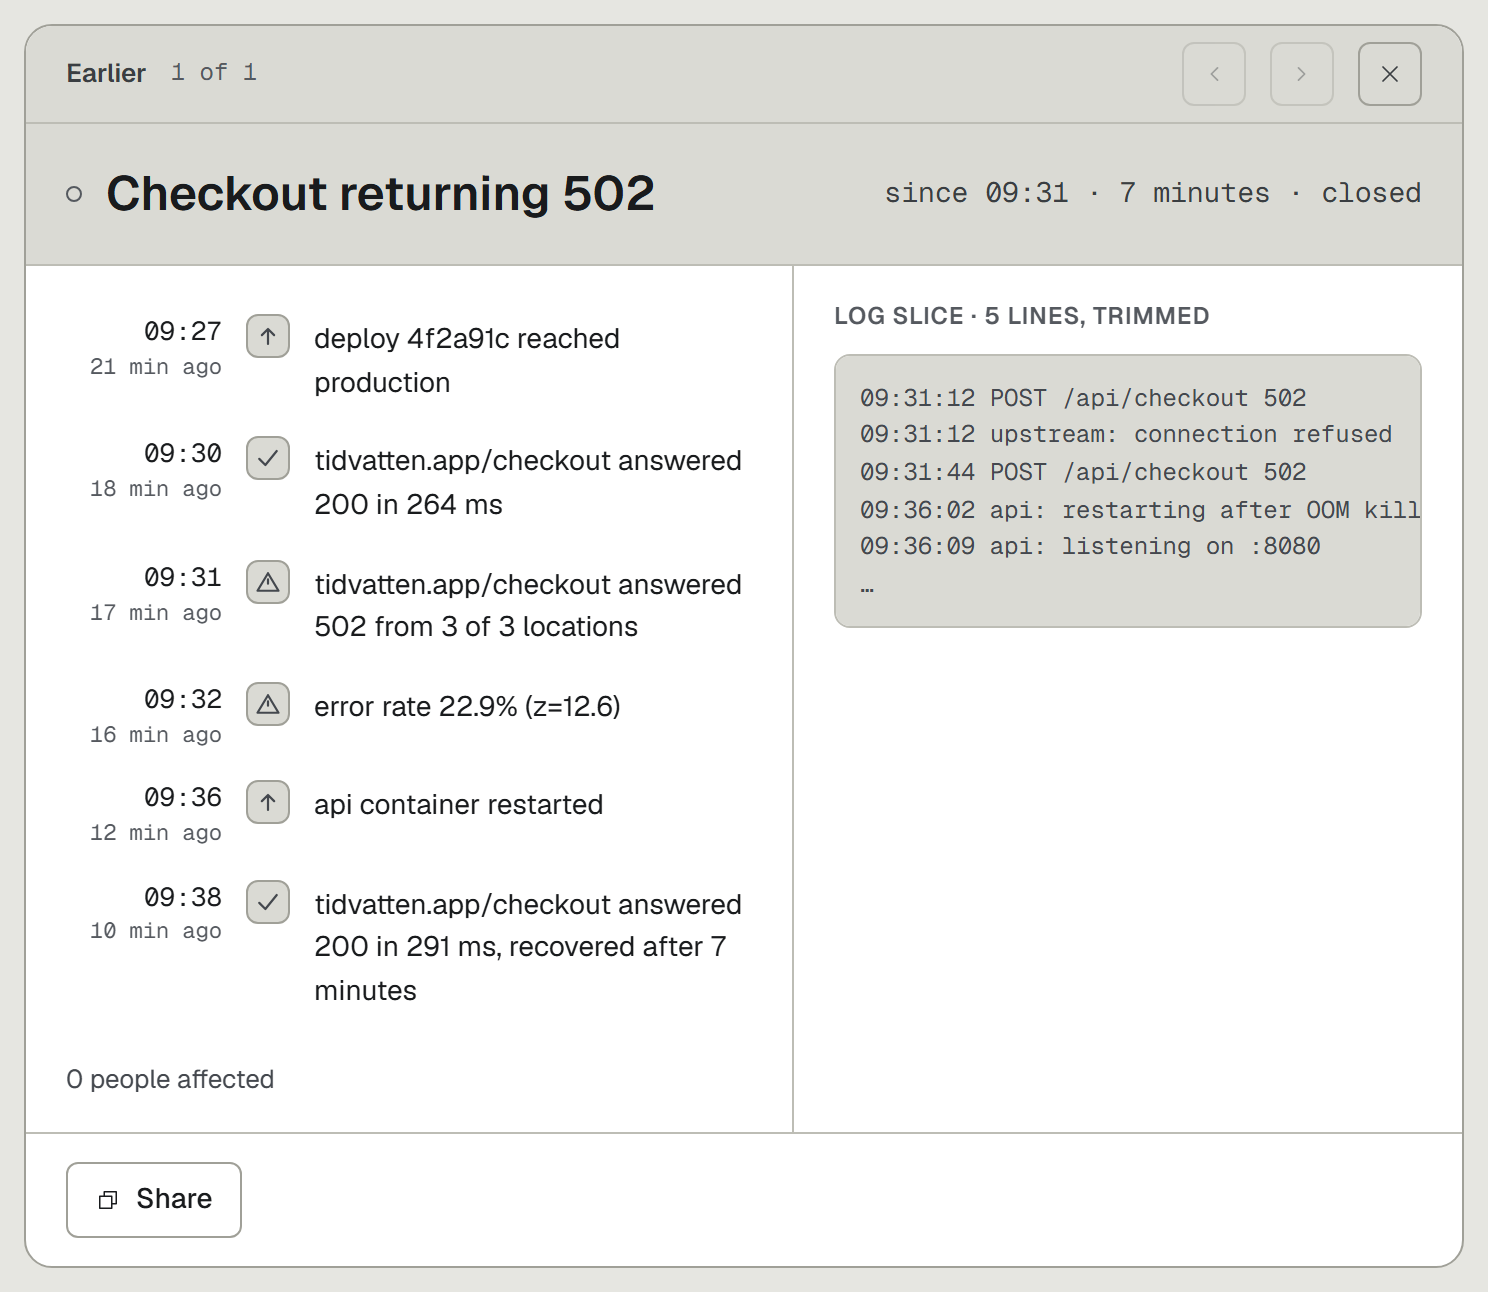
UpControl records every step on the incident's timeline: when it opened, who acknowledged it and when, and when it resolved. That's your time to know and your time to recover, with no spreadsheet.
It also cuts out the detective work. The incident arrives with the error, the log lines around it and the deploy that came right before it, so "what changed?" is answered before anyone asks.